Figure 4: Gene programs resolve T cell states below the level of lineage
Ziang Zhang
Last updated: 2026-09-10
Checks: 7 0
Knit directory:
immgenT-GP-analysis/analysis/
This reproducible R Markdown analysis was created with workflowr (version 1.7.2). The Checks tab describes the reproducibility checks that were applied when the results were created. The Past versions tab lists the development history.
Great! Since the R Markdown file has been committed to the Git repository, you know the exact version of the code that produced these results.
Great job! The global environment was empty. Objects defined in the global environment can affect the analysis in your R Markdown file in unknown ways. For reproduciblity it’s best to always run the code in an empty environment.
The command set.seed(1) was run prior to running the
code in the R Markdown file. Setting a seed ensures that any results
that rely on randomness, e.g. subsampling or permutations, are
reproducible.
Great job! Recording the operating system, R version, and package versions is critical for reproducibility.
Nice! There were no cached chunks for this analysis, so you can be confident that you successfully produced the results during this run.
Great job! Using relative paths to the files within your workflowr project makes it easier to run your code on other machines.
Great! You are using Git for version control. Tracking code development and connecting the code version to the results is critical for reproducibility.
The results in this page were generated with repository version dca7ffb. See the Past versions tab to see a history of the changes made to the R Markdown and HTML files.
Note that you need to be careful to ensure that all relevant files for
the analysis have been committed to Git prior to generating the results
(you can use wflow_publish or
wflow_git_commit). workflowr only checks the R Markdown
file, but you know if there are other scripts or data files that it
depends on. Below is the status of the Git repository when the results
were generated:
Ignored files:
    Ignored:    .DS_Store
    Ignored:    .claude/
    Ignored:    analysis/.DS_Store
    Ignored:    analysis/.Rhistory
    Ignored:    analysis/assets/.DS_Store
    Ignored:    captions/
    Ignored:    code/.DS_Store
    Ignored:    code/other/topic_flashier_20250212.R
    Ignored:    code/other/topic_wrapper_20250215_alldata_backfit.sh
    Ignored:    data
    Ignored:    experiments/
    Ignored:    figures/.DS_Store
    Ignored:    figures/final-selected/.DS_Store
    Ignored:    figures/final-selected/Figure 1/.DS_Store
    Ignored:    figures/final-selected/Figure 2/.DS_Store
    Ignored:    figures/final-selected/Figure 5/.DS_Store
    Ignored:    figures/final-selected/Figure S1/.DS_Store
    Ignored:    internal/
    Ignored:    log/
    Ignored:    output/.DS_Store
    Ignored:    output/Figure2/
    Ignored:    plan/
    Ignored:    tables/
    Ignored:    tmp/
Note that any generated files, e.g. HTML, png, CSS, etc., are not included in this status report because it is ok for generated content to have uncommitted changes.
These are the previous versions of the repository in which changes were
made to the R Markdown (analysis/Figure4.Rmd) and HTML
(docs/Figure4.html) files. If you’ve configured a remote
Git repository (see ?wflow_git_remote), click on the
hyperlinks in the table below to view the files as they were in that
past version.
| File | Version | Author | Date | Message |
|---|---|---|---|---|
| Rmd | dca7ffb | Ziang Zhang | 2026-09-10 | Strip the code-narrating prose from every page; fold code chunks by default |
| html | 54718c4 | Ziang Zhang | 2026-09-10 | Build site: the four mean-loading heatmaps without their titles |
| html | 936ed6e | Ziang Zhang | 2026-09-10 | Build site: Extended Data 2d without the DP lineage |
| html | 59021bf | Ziang Zhang | 2026-09-10 | Build site: Extended Data 1-6 after removing the structure-plot figure |
| Rmd | c21f51f | Ziang Zhang | 2026-09-10 | Remove the per-lineage structure-plot figure; keep its record for Figure 4 |
| html | 60125af | Ziang Zhang | 2026-09-10 | Build site: Figure 4b on the shared column colours |
| Rmd | 8eacf9c | Ziang Zhang | 2026-09-10 | Figure 4b: the column colours and order of Figure 1d and ED Fig 2d |
| html | 88ee847 | Ziang Zhang | 2026-09-10 | Build site: Figure 4b without the miniverse clusters |
| Rmd | 75c6f9b | Ziang Zhang | 2026-09-10 | Figure 4b: drop the miniverse clusters, as Figure 1d and ED Fig 2d do |
| html | 5874416 | Ziang Zhang | 2026-09-10 | Build site: main Figure 4 inserted, Extended Data back to 1-7 |
| Rmd | 4307b28 | Ziang Zhang | 2026-09-10 | New main Figure 4, and fold the cluster heatmap into Extended Data Figure 2 |
| html | a7a481f | Ziang Zhang | 2026-09-09 | Build site: the rebuilt Figure 1d and the Extended Data renumbering |
| Rmd | c233cd8 | Ziang Zhang | 2026-09-09 | Extended Data reorganisation: split the tissue/cluster figure, renumber 3-8 |
| html | 1e88d7e | Ziang Zhang | 2026-09-04 | Build site: published captions and titles across all 24 pages |
| Rmd | 0267e5b | Ziang Zhang | 2026-09-04 | Captions from the published manuscript; trim editor notes off the page code |
| html | 19c977f | Ziang Zhang | 2026-09-02 | Build site: Extended Data 5-7 renumbered, Figure S5 page rebuilt |
| html | eeca07b | Ziang Zhang | 2026-08-05 | Keep pre-refactor provenance in panel comments off the published pages |
| Rmd | 5651d0e | Ziang Zhang | 2026-08-05 | Extended Data tables: reorder to six, rebuild Table 1, drop internal notes |
| html | cbcec52 | Ziang Zhang | 2026-07-30 | Build site: Extended Data Figure naming |
| Rmd | 66aa029 | Ziang Zhang | 2026-07-30 | Name the Extended Data figures as published on the site |
| html | ac650a0 | Ziang Zhang | 2026-07-30 | Build site: Figure S5 (ex-S6a) and Figure S6 as a-f |
| html | 62e6e83 | Ziang Zhang | 2026-07-29 | Build site: Figure 4 without the TF-GP network |
| Rmd | 77f3337 | Ziang Zhang | 2026-07-29 | Drop Figure 4’s TF-GP network; re-letter 4d/4e to 4c/4d |
| html | ae21d37 | Ziang Zhang | 2026-07-28 | Build site: republish after the reorder commits |
| html | d538aa2 | Ziang Zhang | 2026-07-28 | Build site: reordered Figures 6 / S6 / S3 and the new Figure 7b page |
| html | 029b0ae | Ziang Zhang | 2026-07-28 | Build site. |
| Rmd | 0f5b5da | Ziang Zhang | 2026-07-28 | Align all figure captions with captions_20260728_final.docx |
| html | 3fc3789 | Ziang Zhang | 2026-07-27 | Republish all 24 pages |
| html | 1390a03 | Ziang Zhang | 2026-07-27 | Republish all 24 pages |
| html | adaef21 | Ziang Zhang | 2026-07-27 | Build site: panel fixes and PDF-derived assets |
| html | 5b19858 | Ziang Zhang | 2026-07-27 | Build site. |
| Rmd | 91ee059 | Ziang Zhang | 2026-07-26 | Select each panel’s code block by name, not by line number |
| html | 91ee059 | Ziang Zhang | 2026-07-26 | Select each panel’s code block by name, not by line number |
| Rmd | 620afca | Ziang Zhang | 2026-07-24 | Align Fig3/4/5 section titles with current numbers; reletter Fig4 to a-e |
| html | 620afca | Ziang Zhang | 2026-07-24 | Align Fig3/4/5 section titles with current numbers; reletter Fig4 to a-e |
| Rmd | 2873ad2 | Ziang Zhang | 2026-07-16 | Unify Fig 3/4/5 panel filenames with new figure numbers |
| html | 2873ad2 | Ziang Zhang | 2026-07-16 | Unify Fig 3/4/5 panel filenames with new figure numbers |
| Rmd | b197499 | Ziang Zhang | 2026-07-16 | Restructure main figures (renumber + split Figure 1) |
| html | b197499 | Ziang Zhang | 2026-07-16 | Restructure main figures (renumber + split Figure 1) |
| html | 6d1c6c0 | Ziang Zhang | 2026-07-04 | Fix TableS1 to use non-thymocyte (not healthy-restricted) AUC, matching published Table S1 |
| html | 92021bf | Ziang Zhang | 2026-07-02 | Build site. |
| html | 827c89b | Ziang Zhang | 2026-07-02 | Build site. |
| Rmd | 8ac7f9f | Ziang Zhang | 2026-07-02 | Add data provenance notes to each script; remove conversational |
| Rmd | f9db962 | Ziang Zhang | 2026-07-02 | Simplify layout: drop old code/script folders, rename |
| html | c6e5086 | Ziang Zhang | 2026-07-02 | Build site. |
| html | 5a79883 | Ziang Zhang | 2026-07-02 | Build site. |
| Rmd | 2b0e445 | Ziang Zhang | 2026-07-02 | Fix GitHub source links to point at the new |
| html | cf1d0ac | Ziang Zhang | 2026-07-02 | Build site. |
| Rmd | 06b2461 | Ziang Zhang | 2026-07-02 | Initial commit: immgenT-GP-analysis |
| html | 06b2461 | Ziang Zhang | 2026-07-02 | Initial commit: immgenT-GP-analysis |
All panels are produced by script/Figure4.R.
The code below is shown for reference; the images are its pre-rendered
output.
Setup
suppressPackageStartupMessages({
  library(ggplot2)
  library(ggrepel)
  library(ggrastr)
  library(cowplot)
  library(dplyr)
  library(fastTopics)      # structure_plot()
  library(ComplexHeatmap)
  library(circlize)
  library(grid)
  library(ZemmourLib)      # immgent_colors
})

if (!file.exists("code/R/structure_plot_panels.R")) {
  stop("Run this script from the immgenT-GP-analysis repository root.")
}
source("code/R/structure_plot_panels.R")   # the per-lineage structure plots' rows, GP rule, palette
source("code/R/centered_mean_heatmap.R")   # Extended Data Figure 2d's heatmap rendering
source("code/R/level2_group_palette.R")    # EXCLUDE_LEVEL2_GROUPS, as Figure 1d and ED 2d use

data_path   <- "data/"
figure_path <- "figures/final-selected/Figure 4/"
record_path <- "output/Figure4/"
dir.create(figure_path, recursive = TRUE, showWarnings = FALSE)
dir.create(record_path, recursive = TRUE, showWarnings = FALSE)

# Figure scripts here have been seen to exit 0 having written nothing, so every
# PDF is checked against this timestamp at the end rather than against the exit
# code (script/README.md, "A re-run can silently not write").
run_started_at <- Sys.time()

# ============================================================
# Load data
# ============================================================
seurat_meta <- readRDS(paste0(
  data_path, "igt1_96_withtotalvi20260206_clean_ADTonly.Rds"
))@meta.data
L_pm_filtered <- readRDS(paste0(data_path, "L_pm_filtered.rds"))
seurat_meta_filtered <- seurat_meta[rownames(L_pm_filtered), ]
colnames(L_pm_filtered) <- gsub("^K", "GP", colnames(L_pm_filtered))
if (!all(grepl("^GP[0-9]+$", colnames(L_pm_filtered)))) {
  stop("The loading matrix does not carry K##/GP## column names.")
}

level_1_AUC_list <- readRDS(paste0(
  data_path, "level_1_AUC_list_figure_no_thymocytes_healthy.rds"
))
level_2_AUC_list <- readRDS(paste0(
  data_path, "level_2_AUC_list_figure_no_thymocytes_healthy.rds"
))
colnames(level_1_AUC_list$auc) <- gsub("^K", "GP", colnames(level_1_AUC_list$auc))
colnames(level_2_AUC_list$auc) <- gsub("^K", "GP", colnames(level_2_AUC_list$auc))

# Both AUC matrices index GPs by names taken from the loading matrix, so they
# have to be talking about the same GPs in the same order.
if (!identical(colnames(level_1_AUC_list$auc), colnames(L_pm_filtered)) ||
      !identical(colnames(level_2_AUC_list$auc), colnames(L_pm_filtered))) {
  stop("The AUC matrices and L_pm_filtered do not carry the same GP columns in the same order.")
}

level1_all <- seurat_meta_filtered$annotation_level1
level2_all <- seurat_meta_filtered$annotation_level2
healthy_non_thymocyte <- which(
  seurat_meta_filtered$condition_broad == "healthy" & level1_all != "thymocyte"
)
meta_reference <- seurat_meta_filtered[healthy_non_thymocyte, , drop = FALSE]
L_healthy <- L_pm_filtered[healthy_non_thymocyte, , drop = FALSE]
overall_mean <- colMeans(L_healthy, na.rm = TRUE)

message(sprintf(
  "%d healthy non-thymocyte cells, %d GPs, %d level-2 clusters",
  nrow(L_healthy), ncol(L_healthy), dplyr::n_distinct(meta_reference$annotation_level2)
))
(a) Lineage vs. cluster prediction
# ============================================================
# 4a: Max AUC level-1 vs max AUC level-2
# ============================================================
# Figure 6a and 6d's construction, with their category-count filters kept as
# they are there: level-1 lineages need 1000 cells, level-2 clusters 100.
level_1_small <- table(meta_reference$annotation_level1)
level_1_small <- names(level_1_small[level_1_small < 1000])
level_1_AUC <- level_1_AUC_list$auc[
  !rownames(level_1_AUC_list$auc) %in% level_1_small, , drop = FALSE
]

level_2_small <- table(meta_reference$annotation_level2)
level_2_small <- names(level_2_small[level_2_small < 100])
level_2_AUC <- level_2_AUC_list$auc[
  !rownames(level_2_AUC_list$auc) %in% level_2_small, , drop = FALSE
]

# A high AUC only means "GP predicts this category" when the category's mean
# loading is above the overall mean; the other direction is a GP the category
# lacks. Same masking as Figure 6.
category_mean <- function(labels, categories) {
  t(vapply(categories, function(cat) {
    colMeans(L_healthy[labels == cat, , drop = FALSE], na.rm = TRUE)
  }, numeric(ncol(L_healthy))))
}
level_1_positive <- sweep(
  category_mean(meta_reference$annotation_level1, rownames(level_1_AUC)),
  2, overall_mean, "-"
) > 0
level_2_positive <- sweep(
  category_mean(meta_reference$annotation_level2, rownames(level_2_AUC)),
  2, overall_mean, "-"
) > 0

masked_max <- function(auc, positive) {
  auc[!positive] <- NA
  list(
    value = apply(auc, 2, max, na.rm = TRUE),
    name = apply(auc, 2, function(x) rownames(auc)[which.max(x)])
  )
}
l1_max <- masked_max(level_1_AUC, level_1_positive)
l2_max <- masked_max(level_2_AUC, level_2_positive)

df_a <- data.frame(
  Factor = colnames(level_1_AUC),
  annotation_Level1 = l1_max$name,
  annotation_Level2 = l2_max$name[colnames(level_1_AUC)],
  Max_AUC_Level1 = l1_max$value,
  Max_AUC_Level2 = l2_max$value[colnames(level_1_AUC)],
  stringsAsFactors = FALSE
) |>
  dplyr::mutate(residual = Max_AUC_Level2 - Max_AUC_Level1)

# Figure 6a's highlight rule verbatim: AUC > 0.9 on either axis, coloured by
# which of the two maxima is the larger. Only the labelling differs -- GP names,
# not each point's top categories.
highlighted <- df_a |>
  dplyr::filter(is.finite(residual), Max_AUC_Level1 > 0.9 | Max_AUC_Level2 > 0.9) |>
  dplyr::pull(Factor)

label_above <- df_a |>
  dplyr::filter(Factor %in% highlighted, residual > 0) |>
  dplyr::mutate(
    label_text = Factor
  )
label_below <- df_a |>
  dplyr::filter(Factor %in% highlighted, residual <= 0) |>
  dplyr::mutate(
    label_text = Factor
  )
message(sprintf(
  "a: %d of %d GPs highlighted (%d above the diagonal, %d on or below)",
  length(highlighted), nrow(df_a), nrow(label_above), nrow(label_below)
))

axis_limits <- function(x, pad = 0.04) {
  x <- x[is.finite(x)]
  c(min(x) - pad, max(x) + pad)
}

p_4a <- ggplot(df_a, aes(Max_AUC_Level1, Max_AUC_Level2)) +
  geom_point(alpha = 0.3, size = 1.8) +
  geom_point(data = label_above, color = "#1f78b4", alpha = 0.8, size = 1.8) +
  geom_point(data = label_below, color = "#e31a1c", alpha = 0.8, size = 1.8) +
  geom_abline(slope = 1, intercept = 0, linetype = "dashed", color = "black") +
  coord_cartesian(
    xlim = axis_limits(df_a$Max_AUC_Level1),
    ylim = axis_limits(df_a$Max_AUC_Level2),
    expand = FALSE, clip = "off"
  ) +
  labs(
    x = "Max AUC (Level-1)", y = "Max AUC (Level-2)",
    title = "Max AUC: Level-1 vs Level-2"
  ) +
  theme_minimal(base_size = 13) +
  theme(plot.margin = margin(10, 40, 10, 40)) +
  geom_text_repel(
    seed = 42, data = label_above, aes(label = label_text), color = "#1f78b4",
    size = 2.5, lineheight = 0.85, direction = "y", nudge_x = -0.035,
    segment.color = "#1f78b4",
    arrow = arrow(length = unit(0.008, "npc"), type = "closed", angle = 20),
    force = 3, force_pull = 0.1, box.padding = 0.4, point.padding = 0.15,
    max.time = 10, max.iter = 2e4, max.overlaps = 20,
    min.segment.length = 0.01, segment.alpha = 0.7
  ) +
  geom_text_repel(
    seed = 42, data = label_below, aes(label = label_text), color = "#e31a1c",
    size = 2.5, lineheight = 0.85, direction = "y", nudge_x = 0.035,
    segment.color = "#e31a1c",
    arrow = arrow(length = unit(0.008, "npc"), type = "closed", angle = 20),
    force = 3, force_pull = 0.1, box.padding = 0.4, point.padding = 0.15,
    max.time = 10, max.iter = 2e4, max.overlaps = 20,
    min.segment.length = 0.01, segment.alpha = 0.7
  )
ggsave(paste0(figure_path, "4a.pdf"), p_4a, width = 8, height = 8, dpi = 300)

write.csv(
  df_a[order(-df_a$Max_AUC_Level2), c(
    "Factor", "Max_AUC_Level1", "annotation_Level1",
    "Max_AUC_Level2", "annotation_Level2", "residual"
  )],
  file.path(record_path, "4a_max_auc_level1_level2.csv"),
  row.names = FALSE
)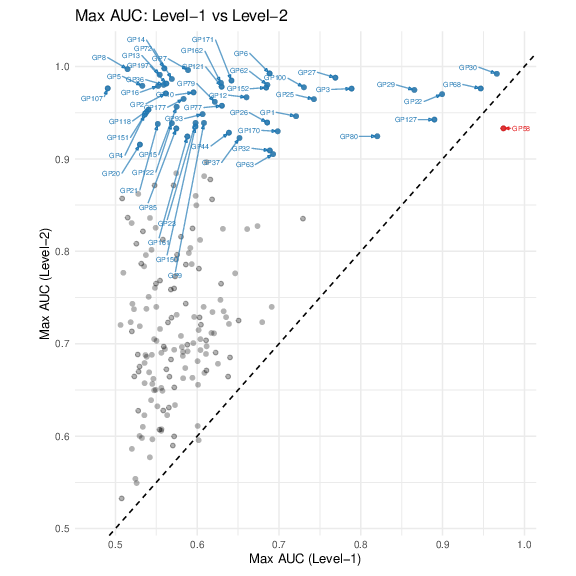
Fig. 4a. Scatterplot showing each GP’s prediction (AUC) of level 1 lineage (x-axis) versus level 2 cluster (y-axis), in healthy non-thymocyte cells. Each point is one GP; the dashed line is the identity. GPs reaching AUC > 0.9 on either axis are colored and labelled: blue where the cluster AUC is the larger of the two, red where the lineage AUC is. Most GPs sit above the identity line, predicting a cluster better than any whole lineage.
(b) The cluster-associated GPs across clusters
# ============================================================
# 4b: the same GPs as a heatmap, level-2 columns grouped by level 1
# ============================================================
cells_drawn <- sort(unlist(lineage_cells_drawn, use.names = FALSE))
labels_drawn <- droplevels(factor(level2_all[cells_drawn]))
heat_means <- mean_loading_by_group(
  L_pm_filtered[cells_drawn, gp_union, drop = FALSE], labels_drawn
)
heat_raw <- heat_means$matrix          # GPs x clusters
heat_centered <- center_by_gp_mean(heat_raw)

# Figure 1's level-1 order, minus DP and thymocytes, which these rows exclude.
level1_order <- c("CD8", "CD4", "Treg", "gdT", "CD8aa", "Tz", "DN")
level2_group_level1 <- level2_to_level1_map(
  meta_reference, colnames(heat_raw), level1_order
)
level2_group_group <- level2_to_group_map(meta_reference, colnames(heat_raw))

# Columns follow Figure 1d and Extended Data Figure 2d exactly: lineage, then
# annotation_level2_group as a contiguous block, then cluster alphabetically --
# so each lineage's ".P" cluster sits at the end of its lineage rather than
# mid-alphabet, and the level2_group bar reads as blocks. GP rows then follow
# the columns, in dominant-cluster blocks.
heat_order <- dominant_group_order(
  heat_raw,
  level2_group_block_order(
    colnames(heat_raw), level2_group_level1, level2_group_group, level1_order
  )
)

level1_palette <- ZemmourLib::immgent_colors$level1[level1_order]

centered_color_limit <- 0.2
render_centered_heatmap(
  heat_centered,
  NULL,
  "cluster (annotation_level2)",
  paste0(figure_path, "4b.pdf"),
  heat_order$row_order,
  heat_order$column_order,
  centered_color_limit,
  sprintf(
    paste0(
      "%d GPs with AUC > %.1f in some cluster; miniverse (.wM) clusters excluded\n",
      "level2 columns: level1 order (%s); level2_group blocks, alphabetical ",
      "within block; GP rows: dominant-cluster blocks"
    ),
    nrow(heat_centered), structure_plot_auc_threshold,
    paste(level1_order, collapse = ", ")
  ),
  group_level1 = level2_group_level1,
  level1_palette = level1_palette,
  group_annotation = level2_group_group,
  group_annotation_palette = LEVEL2_GROUP_COLORS[LEVEL2_GROUP_ORDER]
)

write.csv(
  data.frame(gp = rownames(heat_centered), heat_centered, check.names = FALSE),
  file.path(record_path, "4b_row_centered_mean_loading.csv"), row.names = FALSE
)
write.csv(
  data.frame(
    cluster = heat_means$counts$group,
    level1 = unname(level2_group_level1[heat_means$counts$group]),
    n_cells = heat_means$counts$n_cells
  ),
  file.path(record_path, "4b_column_cells.csv"), row.names = FALSE
)
| Version | Author | Date |
|---|---|---|
| 54718c4 | Ziang Zhang | 2026-09-10 |
| 8eacf9c | Ziang Zhang | 2026-09-10 |
| 75c6f9b | Ziang Zhang | 2026-09-10 |
| 5874416 | Ziang Zhang | 2026-09-10 |
| 7102598 | Ziang Zhang | 2026-07-27 |
| 6c1a613 | Ziang Zhang | 2026-07-27 |
| bf7afcf | Ziang Zhang | 2026-07-27 |
| ea3ecc2 | Ziang Zhang | 2026-07-27 |
| 620afca | Ziang Zhang | 2026-07-24 |
| b197499 | Ziang Zhang | 2026-07-16 |
| 78e3bba | Ziang Zhang | 2026-07-03 |
| 06b2461 | Ziang Zhang | 2026-07-02 |
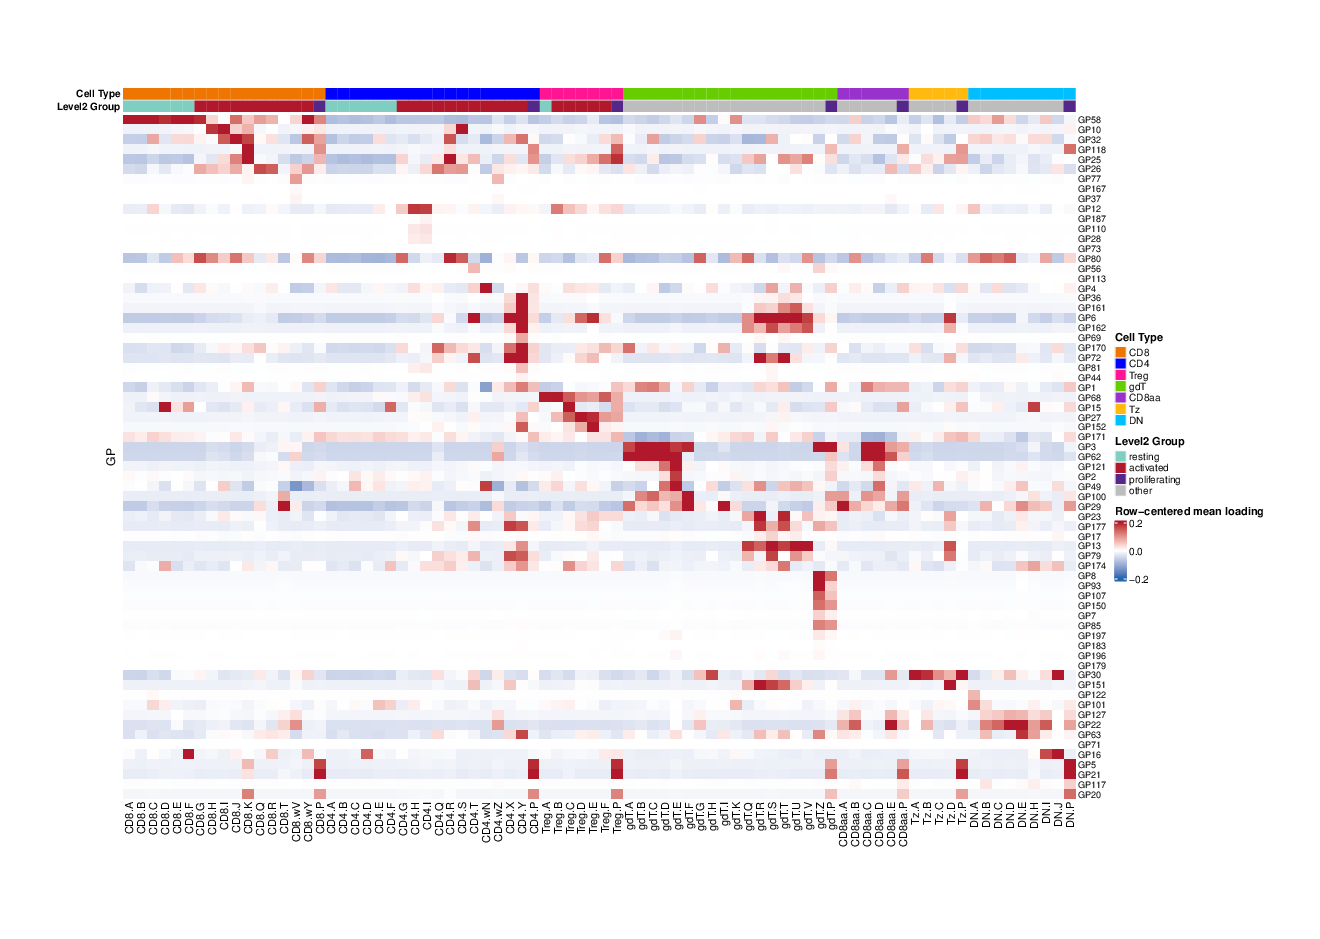
Fig. 4b. Heatmap of mean GP activity per level 2
cluster, for the 69 GPs that reach AUC > 0.9 in at least one cluster.
Each row is centered on that GP’s mean across the clusters shown (blue,
below; red, above; saturating at 0.2). Columns are the 80 clusters with
at least 100 healthy non-thymocyte cells, ordered by lineage (Cell Type
bar), then by activation state (Level2 Group bar) as a contiguous block,
then alphabetically; rows are grouped by the cluster in which the GP is
most active. Colors and column order follow Figure 1d and Extended Data
Fig. 2d, and as there the miniverse (.wM) clusters are
excluded.
(c) Mean GP activity of the Treg clusters
# ============================================================
# 4c: one stacked bar of mean loadings per level-2 cluster, the Treg row
# ============================================================
# The Treg structure-plot row with one bar per cluster, holding that
# cluster's mean loading per GP instead of one bar per cell -- the average of
# that row's bars. Same GPs (the 11 with AUC > 0.9 in some Treg cluster), same
# per-row palette, same cells, minus Treg.wM.
#
# Bars are raw mean loadings, not rescaled to a common height: that is what
# makes them the average of those bars, since structure_plot() does not
# renormalize a subset of topics either. A tall bar means the cluster carries
# more total activity over the row's GPs, not just a different mix.
#
#
# Unlike 4d and the structure plots this panel is not drawn at the structure
# plot's 16 x 3 in: a chart of seven bars does not need a structure plot's
# width, and Ziang asked for tall and narrow.
bar_figure_width <- 5.5  # inches
bar_figure_height <- 7

# Mean loading per cluster over the row's GPs, plus the record of every segment.
bar_means <- function(lineage) {
  gps_lineage <- panel_gps[[lineage]]
  means <- mean_loading_by_cluster(lineage_cells_drawn[[lineage]], gps_lineage)
  bar_matrix <- means$matrix
  totals <- rowSums(bar_matrix)
  if (any(!is.finite(totals)) || any(totals <= 0)) {
    stop(sprintf("row %s: a cluster has no loading at all.", lineage))
  }

  # This row's colours, assigned from the top of the palette without reference
  # to any other row -- the same per-row rule the structure plots use, so
  # colour means different GPs in different rows.
  colors_lineage <- structure_plot_row_colors(gps_lineage)
  if (!identical(names(colors_lineage), colnames(bar_matrix))) {
    stop(sprintf("row %s: palette order does not match its GP columns.", lineage))
  }

  long <- data.frame(
    cluster = factor(
      rep(rownames(bar_matrix), times = ncol(bar_matrix)),
      levels = rownames(bar_matrix)
    ),
    gp = factor(
      rep(colnames(bar_matrix), each = nrow(bar_matrix)),
      levels = colnames(bar_matrix)
    ),
    value = as.vector(bar_matrix),
    stringsAsFactors = FALSE
  )

  record <- data.frame(
    panel = structure_plot_panels[[lineage]],
    lineage = lineage,
    drawn_in_4c = lineage == bar_lineage,
    cluster = as.character(long$cluster),
    n_cells = means$counts[match(long$cluster, rownames(bar_matrix))],
    gp = as.character(long$gp),
    color = unname(colors_lineage[as.character(long$gp)]),
    mean_loading = long$value,
    # The same segment as a share of its cluster's total -- the normalized view's
    # number, kept so that variant can be redrawn from the record alone.
    proportion = long$value / totals[as.character(long$cluster)],
    stringsAsFactors = FALSE
  )

  list(long = long, colors = colors_lineage, record = record, gps = gps_lineage)
}

bar_lineage <- "Treg"
bar_data <- lapply(names(structure_plot_panels), bar_means)
names(bar_data) <- names(structure_plot_panels)

drawn <- bar_data[[bar_lineage]]
p_4c <- ggplot(drawn$long, aes(cluster, value, fill = gp)) +
  geom_col(width = 0.85) +
  scale_fill_manual(values = drawn$colors) +
  scale_y_continuous(expand = expansion(mult = c(0, 0.02))) +
  labs(
    x = "", y = "mean loading", fill = "",
    title = sprintf(
      "%s (%d GPs, AUC > %.1f)", bar_lineage, length(drawn$gps),
      structure_plot_auc_threshold
    )
  ) +
  guides(fill = guide_legend(ncol = 1)) +
  cowplot::theme_cowplot(9) +
  theme(
    plot.title = element_text(size = 11, face = "bold"),
    axis.text.x = element_text(size = 7, angle = 45, hjust = 1),
    axis.text.y = element_text(size = 9),
    axis.title = element_text(size = 10, face = "bold"),
    axis.line = element_blank(),
    axis.ticks = element_blank(),
    legend.position = "right",
    legend.key.size = unit(0.3, "cm"),
    legend.text = element_text(size = 7)
  )
ggsave(
  paste0(figure_path, "4c.pdf"), p_4c,
  width = bar_figure_width, height = bar_figure_height, dpi = 300
)

# Every bar segment of all seven rows, raw and as a share of its cluster's
# total; drawn_in_4c marks the row this panel shows.
bar_record <- do.call(rbind, lapply(bar_data, `[[`, "record"))
write.csv(bar_record, file.path(record_path, "4c_mean_loading_by_cluster.csv"), row.names = FALSE)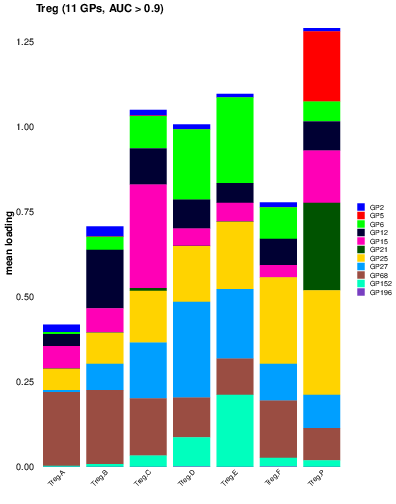
| Version | Author | Date |
|---|---|---|
| 5874416 | Ziang Zhang | 2026-09-10 |
| 62e6e83 | Ziang Zhang | 2026-07-29 |
| 7102598 | Ziang Zhang | 2026-07-27 |
| 6c1a613 | Ziang Zhang | 2026-07-27 |
| bf7afcf | Ziang Zhang | 2026-07-27 |
| ea3ecc2 | Ziang Zhang | 2026-07-27 |
| 620afca | Ziang Zhang | 2026-07-24 |
| 2873ad2 | Ziang Zhang | 2026-07-16 |
| b197499 | Ziang Zhang | 2026-07-16 |
| 78e3bba | Ziang Zhang | 2026-07-03 |
| 06b2461 | Ziang Zhang | 2026-07-02 |
Fig. 4c. Mean GP activity of each Treg cluster, for
the 11 GPs reaching AUC > 0.9 in at least one Treg cluster. Each bar
is one cluster and is stacked by GP, so its height is that cluster’s
total mean loading over these GPs. Clusters with fewer than 100 healthy
non-thymocyte cells, and the miniverse (.wM) cluster, are
not shown.
(d) The same GPs and cells, cell by cell
# ============================================================
# 4d: the Treg structure-plot row on its own
# ============================================================
# structure_plot_record.R's loop body for one lineage, unchanged including its seeds and its
# 2000-cell cap, so this is that row and not a redrawing of it.
d_lineage <- "Treg"
gps_d <- panel_gps[[d_lineage]]
cells_d <- healthy_non_thymocyte[level1_all[healthy_non_thymocyte] == d_lineage]
cluster_size_d <- table(droplevels(factor(level2_all[cells_d])))
small_d <- names(cluster_size_d)[cluster_size_d < structure_plot_min_cluster_cells]
cells_d <- cells_d[!level2_all[cells_d] %in% small_d]
cells_d <- drop_miniverse(cells_d)   # as in 4b and 4c

set.seed(1234)
keep_d <- unlist(lapply(
  split(seq_along(cells_d), level2_all[cells_d]),
  function(idx) {
    if (length(idx) > structure_plot_max_cells_per_cluster) {
      sample(idx, structure_plot_max_cells_per_cluster)
    } else {
      idx
    }
  }
))
cells_d <- cells_d[keep_d]

fit_d <- L_pm_filtered[cells_d, gps_d, drop = FALSE]
colors_d <- structure_plot_row_colors(gps_d)
if (!identical(names(colors_d), colnames(fit_d))) {
  stop("4d: palette order does not match its GP columns.")
}

set.seed(1234)
p_4d <- structure_plot(
  fit_d, topics = gps_d, gap = 40, n = 10000, colors = colors_d,
  grouping = factor(level2_all[cells_d]),
  ggplot_call = rasterized_structure_plot_call
) +
  labs(
    y = "membership", color = "", fill = "",
    title = sprintf(
      "%s (%d GPs, AUC > %.1f)", d_lineage, length(gps_d), structure_plot_auc_threshold
    )
  ) +
  guides(fill = guide_legend(ncol = 2), color = guide_legend(ncol = 2)) +
  theme(
    plot.title = element_text(size = 11, face = "bold"),
    axis.text.x = element_text(size = 6, angle = 45, hjust = 1),
    axis.text.y = element_text(size = 9),
    axis.title = element_text(size = 10, face = "bold"),
    legend.position = "right",
    legend.key.size = unit(0.25, "cm"),
    legend.text = element_text(size = 5),
    legend.spacing.y = unit(0.02, "cm")
  )
ggsave(
  paste0(figure_path, "4d.pdf"), p_4d,
  width = structure_plot_width, height = structure_plot_row_height,
  dpi = 300, limitsize = FALSE
)
| Version | Author | Date |
|---|---|---|
| 5874416 | Ziang Zhang | 2026-09-10 |
| 62e6e83 | Ziang Zhang | 2026-07-29 |
| 7102598 | Ziang Zhang | 2026-07-27 |
| 6c1a613 | Ziang Zhang | 2026-07-27 |
| bf7afcf | Ziang Zhang | 2026-07-27 |
| ea3ecc2 | Ziang Zhang | 2026-07-27 |
| 620afca | Ziang Zhang | 2026-07-24 |
| 2873ad2 | Ziang Zhang | 2026-07-16 |
| b197499 | Ziang Zhang | 2026-07-16 |
| 78e3bba | Ziang Zhang | 2026-07-03 |
| 06b2461 | Ziang Zhang | 2026-07-02 |
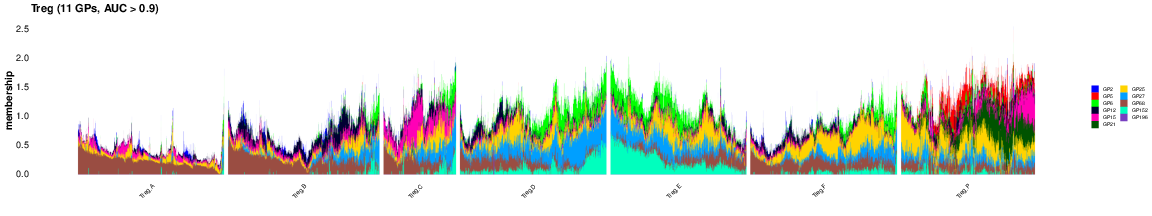
Fig. 4d. Structure plot of the same GPs in the same cells at single-cell resolution: each bar is one cell, colored by its GP membership and grouped by cluster. Colors match (c). Panel (c) is the per-cluster average of these bars.
sessionInfo()R version 4.5.1 (2025-06-13)
Platform: aarch64-apple-darwin20
Running under: macOS Sequoia 15.6.1
Matrix products: default
BLAS: /System/Library/Frameworks/Accelerate.framework/Versions/A/Frameworks/vecLib.framework/Versions/A/libBLAS.dylib
LAPACK: /Library/Frameworks/R.framework/Versions/4.5-arm64/Resources/lib/libRlapack.dylib; LAPACK version 3.12.1
locale:
[1] en_CA/en_CA/en_CA/C/en_CA/en_CA
time zone: America/Chicago
tzcode source: internal
attached base packages:
[1] stats graphics grDevices utils datasets methods base
loaded via a namespace (and not attached):
[1] vctrs_0.7.3 cli_3.6.6 knitr_1.50 rlang_1.2.0
[5] xfun_0.55 stringi_1.8.9 otel_0.2.0 promises_1.5.0
[9] jsonlite_2.0.0 workflowr_1.7.2 glue_1.8.1 rprojroot_2.1.1
[13] git2r_0.36.2 htmltools_0.5.9 httpuv_1.6.16 sass_0.4.10
[17] rmarkdown_2.30 evaluate_1.0.5 jquerylib_0.1.4 tibble_3.3.0
[21] fastmap_1.2.0 yaml_2.3.12 lifecycle_1.0.5 whisker_0.4.1
[25] stringr_1.6.0 compiler_4.5.1 fs_1.6.6 Rcpp_1.1.1-1.1
[29] pkgconfig_2.0.3 later_1.4.4 digest_0.6.39 R6_2.6.1
[33] pillar_1.11.1 magrittr_2.0.5 bslib_0.9.0 tools_4.5.1
[37] cachem_1.1.0